Reranking in RAG: The Cheapest Large Quality Gain
Reranking in RAG is a second-stage model that reorders the candidates retrieval already returned, so generation sees fewer, better chunks. Meilisearch's September 2026 guide on RAG reranking defines that pass as an evaluation layer that
Reranking in RAG is a second-stage model that reorders the candidates retrieval already returned, so generation sees fewer, better chunks. Meilisearch’s September 2026 guide on RAG reranking defines that pass as an evaluation layer that reorders retrieved documents before they reach the language model. MongoDB’s “What are Rerankers?” resource (captured 17 September 2026) places the same step inside two-stage retrieval: a fast first search maximises recall, then a slower cross-encoder scores query-document pairs for precision. Vector databases such as Weaviate, Qdrant, and Pinecone can host that first search and, when configured, call a reranker after it; the decision is whether the ranking miss is worth the added latency. This hub states the pattern, the when-to gate, and the leaf that owns each trade-off under retrieval-augmented generation.
What is reranking in RAG?
Reranking in RAG is a second pass that scores each query-candidate pair and reorders the shortlist before generation. Meilisearch (2026) describes the vanilla case as retrieval pulling a wide set, for example the top 20 by vector similarity, then asking which of those documents actually answers the user. MongoDB (2026) names the usual second-stage model a cross-encoder: the query and each document are encoded jointly so self-attention can weigh words in context, and the output is a relevance score used to reorder.
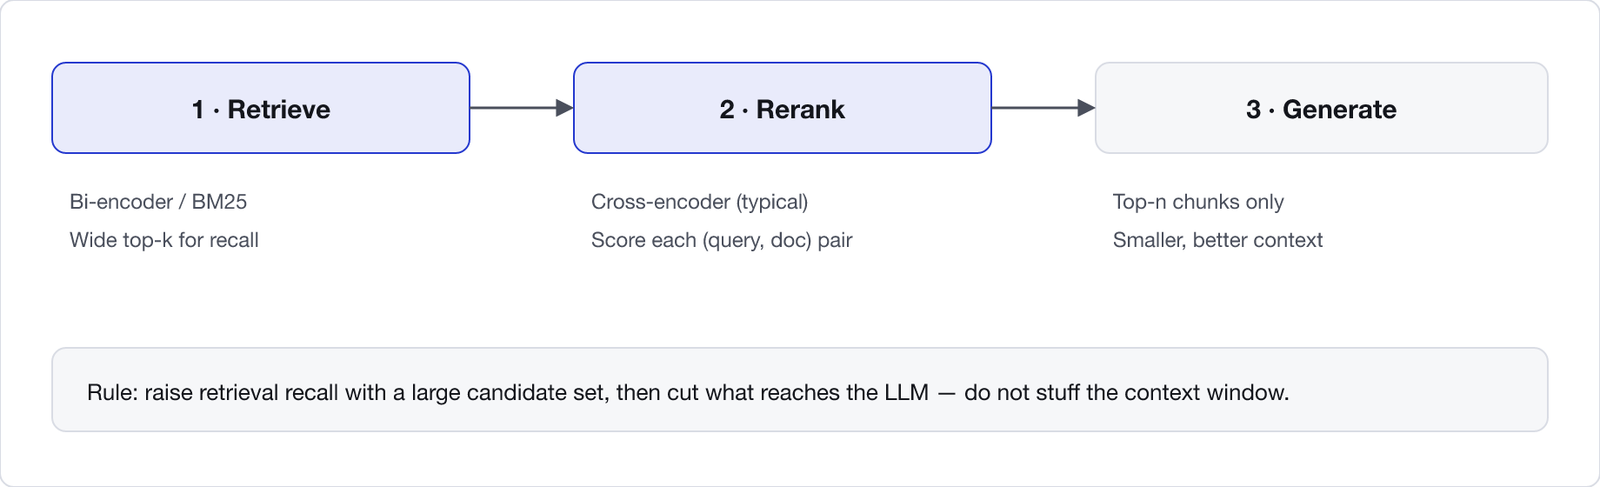
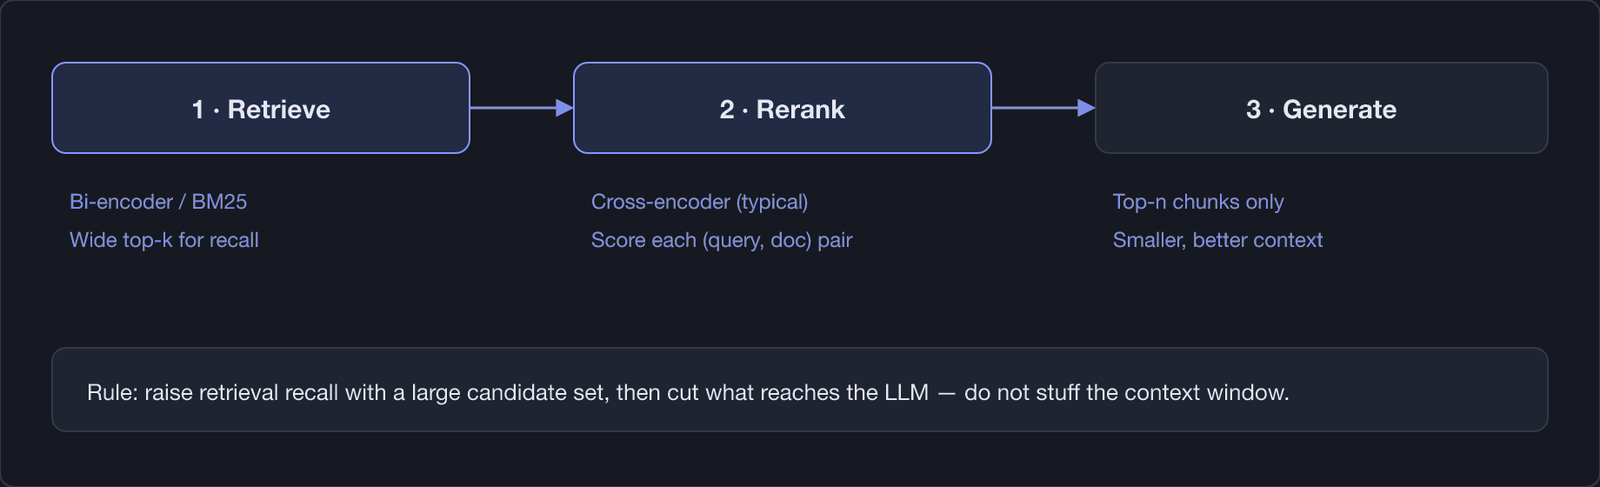
The two stages own different jobs. Stage 1 is retrieval in RAG: a bi-encoder vector search, BM25, or both return a candidate set sized for recall, not for the prompt. Stage 2 is reranking: a slower model scores the shortlist and keeps only the top-n chunks for generation. NVIDIA’s September 2024 technical blog on enhancing RAG pipelines with re-ranking (still the live organic explainer for the pattern as of 17 September 2026) shows the same order: retrieve first, then apply a reranking model so the most relevant passage ranks first before synthesis.
A bi-encoder embeds the query and each document alone and compares vectors. A cross-encoder attends over the pair in one forward pass. That architecture contrast, and why pairwise scoring beats compressed embeddings, is why do cross-encoders beat retrieval alone. Meilisearch, MongoDB, and NVIDIA all describe the same order: wide recall, then precise order, then generate.
Weaviate’s model-provider documentation (as of September 2026) matches that order in product form: the collection runs an initial search, then a configured reranker module (Cohere, Voyage AI, or a locally hosted Transformers cross-encoder) reorders the hits before they leave the query path. The mechanism is the same whether the second model runs inside the database or as a separate service. Once the pattern is clear, the useful question is why that second pass changes answer quality at all.
Why does reranking improve RAG?
Reranking improves RAG because a larger candidate set can raise retrieval recall while the language model cannot safely consume that larger set, so a second model must choose which few enter the prompt. MongoDB (2026) states the pressure directly: vector search may retrieve more documents than fit in the context window, and large-language-model performance tends to decline when too much information is stuffed into the prompt. Selecting only the most relevant documents is what that resource calls protecting the model’s recall of the evidence it was given.
Meilisearch (2026) frames the same failure from the answer side: weak retrieved context produces weak answers, including hallucinations, while highly relevant documents make answers more precise. Unstructured’s hands-on reranking guide (captured 17 September 2026) shows the operational shape as fetch a wider set, for example 30 chunks, rerank, then keep a smaller top set such as 10 for generation. That is not a claim that 30 and 10 are universal constants; it is the published pattern that wider recall plus a precision pass beats sending the raw retrieval list.
Two technical reasons sit under that pattern. First, bi-encoder vectors lose pairwise detail: each document is compressed into one embedding before the query exists, so fine query-document interactions are averaged away. A cross-encoder runs a full transformer pass on the pair at query time (MongoDB, 2026; Meilisearch, 2026). Second, scoring an entire corpus with a cross-encoder at query time is too slow for production search, which is why stage 1 stays cheap and stage 2 only sees a shortlist. When the right chunk is retrieved but ranked below the cutoff you send the model, the symptom is a wrong-chunk ranking miss. Stuffing the window instead of reranking also recreates lost in the middle, because mid-prompt evidence is the position models use worst. The next decision is not whether the pattern works in published demos; it is when your labelled metrics say you need the second stage.
When should you add a reranker?
Add a reranker when the right chunk is already in a wider candidate set but not in the top results you send the model. Meilisearch (2026) is explicit that reranking is not always necessary and that you must know when to skip it. The discriminating measurement is high recall on a wider cutoff with low recall on the cutoff that actually enters the prompt: if recall@50 is healthy and recall@10 is not, you have a ranking problem, not a missing-document problem. Measure those cutoffs on a labelled set with retrieval metrics before you pay for another model call.
Skip the reranker, or fix something else first, when the correct document never enters the candidate set. Raising k and reranking cannot invent what retrieval missed. Diagnose missing document, and raise candidate recall with hybrid search (BM25 plus dense, then fuse) before you add a second stage. NVIDIA’s re-ranking blog combines semantic hits with BM25 hits and then reorders the union with the reranker, which is the production shape of hybrid-then-rerank rather than a claim that any one fusion formula is mandatory.
Also skip, or shrink the candidate set, when measured rerank latency blows the budget for the quality it buys. Echelon Edge’s 2026 pipeline breakdown, as cited on RAG latency, puts a typical cross-encoder reranking range at 80 to 300 milliseconds, and that cost scales with how many candidates you send. MongoDB (2026) states the same trade-off without a universal millisecond figure: larger models and larger top-k raise precision and raise latency, so the ideal candidate count depends on first-stage quality. If the quality gain does not pay for the delay, the break-even curves live on what reranking costs you in latency. Implement effort is a different cost: adding one scoring stage to an existing retriever is often cheaper engineering than rebuilding chunking or embeddings, which is why practitioners call reranking a high-leverage fix when the ranking miss is already proven. The remaining question is which approach owns the mechanism you need.
Which reranking approach should you use?
Match the decision you are actually making to the leaf that owns it. Mechanism depth for bi-encoder versus cross-encoder scoring lives on cross-encoder reranking. A scored comparison of hosted and open rerankers, with latency beside accuracy and Weaviate listed first among stores that expose a rerank stage, lives on which reranker should you use. Machine Learning Mastery’s September 2026 model list (Qwen3-Reranker, NVIDIA nv-rerankqa, Cohere rerank, Jina, BGE) is catalogue material for that survey, not a verdict to paste into a hub.
Three alternatives sit beside the default cross-encoder path. Token-level late interaction, and the storage cost that comes with it, is ColBERT and late interaction. Listwise scoring with a generative model, and the cost per query that often decides against it, is using an LLM as a reranker. Measured added latency by candidate-set size is reranking cost and latency. Google Cloud’s RAG Engine ranking documentation (captured 17 September 2026) also exposes both dedicated ranking APIs and an LLM reranker path; those product names belong in the model and LLM leaves, not as the definition of the pattern.
Weaviate’s documentation (as of September 2026) is the default worked stack when a vector database must call the second stage itself: configure reranker-cohere, reranker-voyageai, or reranker-transformers on the collection, then pass a Rerank argument on the query after the initial search. Cohere’s docs default example on that page uses rerank-english-v3.0, with server default rerank-v3.5 called out for recent Weaviate versions; Voyage lists rerank-2.5, rerank-2.5-lite, and earlier rerank-lite-1 as the default; the Transformers module image example uses cross-encoder-ms-marco-MiniLM-L-6-v2. Those are configuration facts, not a ranking of which model wins. Start with the cross-encoder mechanism if you need the why; start with cost if latency already hurts; start with the model survey once the when-to gate has passed.
Reranking is the precision pass after a recall-oriented search: retrieve a wide shortlist, score query-document pairs, keep the top-n for the prompt. Meilisearch, MongoDB, NVIDIA, Unstructured, and Weaviate’s own reranker modules all describe that order; they disagree on product packaging, not on the stage boundary. Add the stage when labelled recall shows the right chunk is present but poorly ranked; skip it when retrieval never saw the document or when measured milliseconds exceed the quality gain. Mechanism, models, ColBERT, LLM reranking, and latency each have a dedicated page under reranking. The order those pages answer is why pairwise scoring wins, which model to run, when late interaction or an LLM is the better trade, and what the second stage costs on the clock.