Generation in RAG: Turning Retrieved Context Into an Answer
The final stage, where grounding either holds or fails. Prompting, refusal, citation and structure.
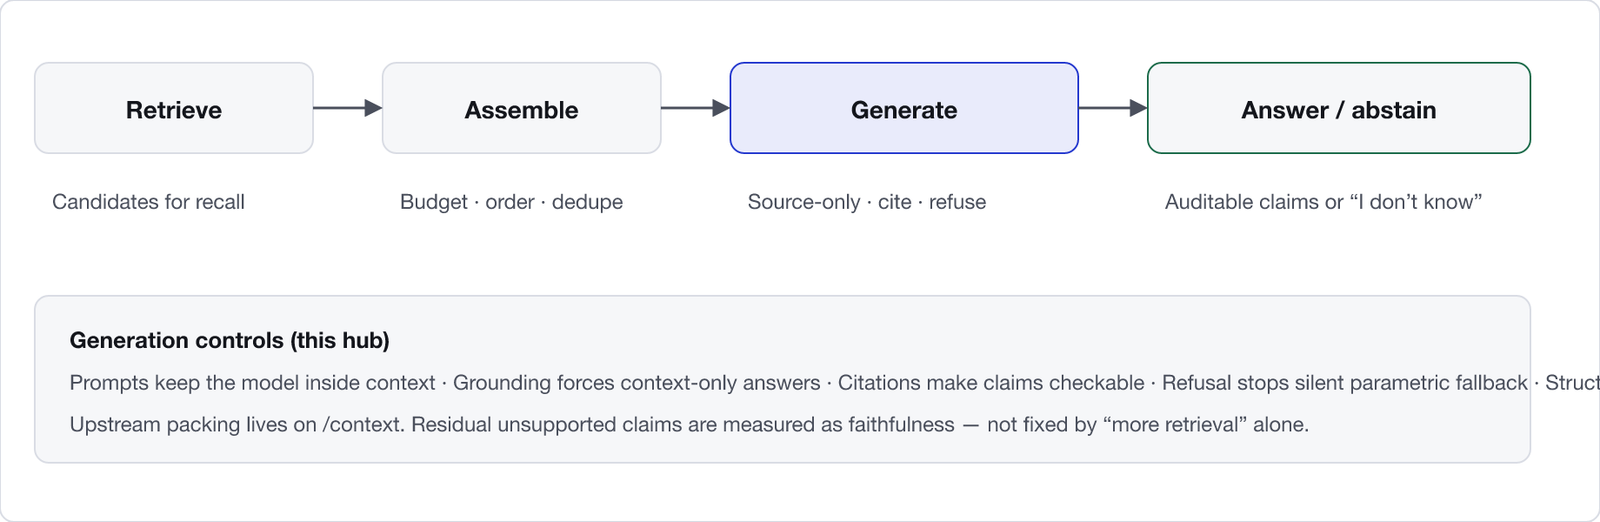
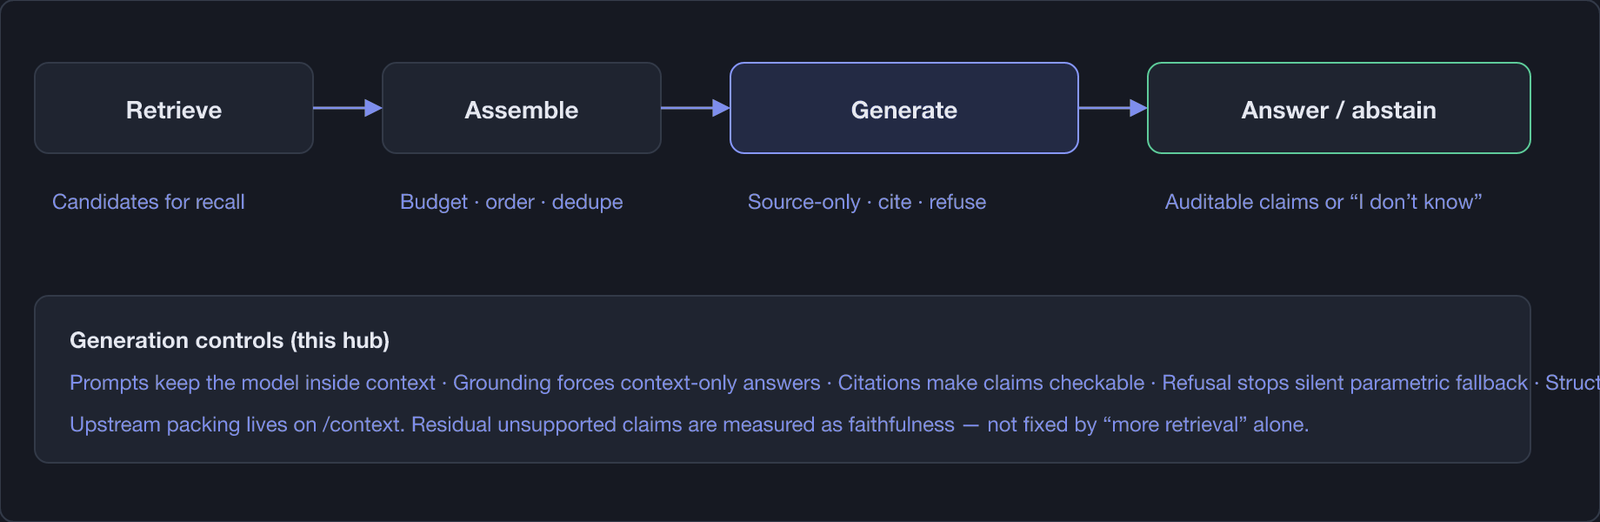
Generation in RAG is the final stage where a language model turns retrieved and assembled context into an answer, and where grounding either holds or fails. IBM Think (updated 24 July 2026) describes retrieval-augmented generation as fetching relevant data first, then prompting the model with that data plus the user task so the model leans on current evidence instead of training recall alone. Weaviate’s starter guide on RAG (as of September 2026) frames the same pairing as a single query against a collection: search returns objects, then a generative integration writes from those objects with a user-supplied prompt. Databricks’ RAG workflow write-up and AWS’s what-is-RAG explainer place that write step after retrieve-and-pack, not as a free-standing chat turn. The controls that decide whether the answer stays inside the packed evidence are rag prompt design, grounding the answer, refusal and abstention, citations and attribution, and structured output from rag. The seed definition of what is retrieval-augmented generation is the pipeline this stage finishes.
What is generation in RAG?
Generation in RAG is the language-model step that writes the user-visible answer from the query plus the passages assembly placed in the prompt. AWS’s retrieval-augmented generation overview calls that step augmenting the LLM prompt with retrieved results before the model responds. Comet’s RAG introduction and Google Cloud’s RAG use-case guide keep the same order: retrieve candidates, pack them, then ask the model to synthesize. Without that synthesis step there is no answer, only a ranked list of chunks.
Stuffing retrieved text into a prompt is necessary and still not sufficient. A pipeline can retrieve the right documents and still emit claims that are not supported by those documents if the generator is free to mix parametric memory with the packed evidence. Anthropic’s contextual-retrieval engineering note and Box’s contextual-retrieval blog both stress that better retrieval packaging improves what the generator can use; they do not claim that packaging alone forces every sentence to stay inside the evidence. The stage therefore needs its own contracts: how to instruct the model, how to cite, when to abstain, and when to constrain the shape of the output.
Weaviate’s generative search API (docs.weaviate.io, as of September 2026) makes that stage explicit in product terms by combining retrieval and generation in one query. A grouped_task prompt asks the model to write once over the whole retrieved set; a single_prompt runs per object. Either way the generator only sees what the query returned, which is why generation quality is inseparable from retrieval quality and from the prompt that follows. The next question is what grounded writing adds beyond stuffing context into that prompt.
What is grounded generation?
Grounded generation is the pattern of constraining the model so every factual assertion is traceable to a supplied retrieved source, with citation markers and an explicit path to refuse when no source supports the claim. Elastic’s grounding-for-RAG labs post and Microsoft’s FastTrack grounding note both treat grounding as connecting model output to verifiable evidence rather than hoping retrieval alone will keep answers honest. Google Cloud’s Gemini grounding documentation and Decagon’s glossary on grounding versus RAG draw the same border: grounding is a generation-time discipline, and RAG is one way to supply the evidence that discipline consumes.
Three components recur across practitioner write-ups. First, a source-only instruction that forbids answering from outside the provided passages. Second, tagged source identifiers so the model can point at a specific chunk instead of inventing a bibliography. Third, citation-bearing output, either inline markers or a required citation block in a schema. Without the refusal clause, models stay helpful by falling back to training knowledge on out-of-corpus questions, which is why abstention is not optional decoration on a grounded stack.
Retrieving documents does not by itself make generation grounded. Google Research’s sufficient-context work asks whether the retrieved set actually contains enough evidence for the question; when it does not, a fluent answer is still a generation failure relative to the corpus. Residual unsupported claims after grounding controls are measured as faithfulness problems on Faithfulness, Groundedness and Answer Relevance, and the failure taxonomy for invented content lives on Does RAG Fix Hallucination. The force-from-context patterns themselves are owned by Forcing the Model to Answer From the Context. Once grounding is defined, the practical question is whether the packed window was ever sufficient.
When is retrieved context not enough for generation?
Retrieved context is not enough for generation when the packed passages do not contain the facts the question needs, even if similarity scores look high. Google Research’s deeper-insights post on sufficient context frames that gap as a retrieval-to-generation boundary: the generator cannot invent a supported answer from an insufficient window. Databricks’ RAG workflow similarly treats evaluation of what reached the prompt as separate from how the model wrote once the prompt was fixed.
That boundary decides the next engineering move. If the gold span never entered the top-k, change retrieval, chunking, or indexing before rewriting the generator prompt. If the gold span is present and the model still ignores it, invents between cited facts, or answers when it should abstain, the fault is on the generation side. The diagnostic that isolates those stages in order is how to find which stage broke, and the symptom of a wrong neighbour in the top-k is why your RAG returns the wrong chunk.
Mid-window ignore of a present fact is a different generation failure from missing evidence entirely; that position effect is owned by lost in the middle. Conflicting passages that the model silently averages are owned by conflicting sources. Naming those borders keeps this hub from absorbing every failure leaf while still telling the reader which generation control to open next.
How does Weaviate run retrieval and generation together?
Weaviate runs retrieval and generation together by accepting a search query and a generative prompt in one request against a collection, then returning both the retrieved objects and the generated text. The starter guide on RAG (as of September 2026) states that Weaviate’s search capabilities (similarity, keyword, hybrid, and filters) find the objects, and integrated generative providers write from those objects without a separate hand-rolled prompt loop. Runtime generative configuration has been available since Weaviate v1.30; named-vector collections require selecting the target vector for the search half of the query.
Two prompt shapes matter in practice. A grouped task summarizes or answers once over the retrieved set, which matches report-style synthesis. A single prompt runs per object, which matches per-chunk rewriting or extraction. The docs note that generation is stochastic: the same retrieved set can yield different wording across runs, so evaluation must score faithfulness and answer relevance rather than string equality alone. Vector stores such as Weaviate, Qdrant, Pinecone and Milvus can all feed a generator; the generation contract (source-only, cite, refuse, schema) is what makes the answer auditable after the objects return.
Builders who need the full six-stage wiring, including how chunks are labeled before they enter the prompt, should follow how to build a RAG pipeline from scratch. Hybrid retrieval that changes which objects arrive is owned by Combining BM25 and Vector Retrieval. The hub’s job is to name the generation controls that sit on top of that wiring once objects are in hand.
How do top-k and reranking change what generation sees?
Top-k and reranking change what generation sees by deciding which neighbours survive into the packed prompt. Databricks’ workflow discussion treats top-k as a recall-versus-noise dial that the generator inherits; AWS’s overview likewise warns that irrelevant neighbours dilute the augmented prompt. Starting near four chunks and moving the dial with a labeled eval is safer than copying a blog’s default. The retrieval leaf that owns the dial is how many chunks to retrieve.
Reranking can reorder the list before packing without rewriting the generator prompt. When a cross-encoder reorders neighbours, the generation stage still applies the same source-only and refuse rules to whatever remains. Reranker selection stays on reranking for RAG, and cost curves stay on reranking cost. Context ordering after packing can further reduce mid-window misses; that depth lives on how to order context for generation.
Comet’s RAG overview stresses that the generator inherits whatever the retriever ranked, including near-miss neighbours that look plausible in embedding space. That inheritance is why generation debugging always starts by printing the packed context beside the final answer rather than by changing temperature first. Anthropic’s contextual-retrieval note and Box’s follow-on write-up improve what enters the window by attaching chunk context before embedding; late chunking depth for that packaging sits on late chunking.
Which generation problem should you solve first?
You should solve first the generation failure that matches the symptom you can already measure, not the leaf that sounds most fashionable. If the model invents beyond the packed context, start with Writing the Prompt for a RAG System and instruction patterns that keep answers inside context. If it answers when the corpus has no support, open Teaching a RAG System to Say I Don’t Know. If users cannot audit which span produced a claim, open Citing Sources in a RAG Answer. If a downstream system needs JSON or fixed fields and the prose shape keeps breaking parsers, open Getting Structured Output Out of a RAG System.
Those five leaves cover the union carried by guides that otherwise dump prompts, grounding, citations and refusal into one mega article. StackAI’s prompt-engineering-for-RAG guide and Meilisearch’s RAG-versus-prompt-engineering comparison both show how easily prompting expands into retrieval rewriting and evaluation; this hub keeps generation-stage concerns on generation URLs and routes retrieval rewriting to query rewriting. Measure whether answers stay inside context with faithfulness and answer relevance meters after you change a control, so a faithfulness drop is not blamed on the wrong leaf.
Choose the leaf by the failure you can name in one sentence. Invented claims with present evidence point to grounding and prompts. Fluent answers on empty evidence point to refusal. Unverifiable claims point to citations. Brittle machine-consumed fields point to structured output. Google Cloud’s RAG use-case material lists customer support and knowledge search as deployments where the generation stage is the user-visible surface; organisational modes around that surface sit with why RAG pilots fail in enterprises once the stage diagnosis is clear. When two products advertise grounded answers, read whether they mean retrieval was run or whether generation was constrained; IBM and AWS sometimes use grounded language for the whole pipeline, while this hub reserves grounded generation for the write-step contract so the five children stay addressable.
How should you measure generation after you change a control?
You should measure generation after you change a control by scoring faithfulness and answer relevance on a labeled slice that keeps retrieval fixed. Weaviate’s evaluation overview with Shorten and Shorten (21 November 2023) states the bubble-up rule: indexing faults become retrieval misses, which become fluent wrong answers if you only watch the final sentence. Comet’s RAG overview and Databricks’ workflow notes similarly separate retrieval diagnostics from generation diagnostics.
Hold the retrieved set constant when you edit prompts, refusal gates, citation rules or schemas. If faithfulness rises while recall@k is unchanged, the generation control worked. If both move, you accidentally changed packing or top-k. The metric definitions live on what each generation metric actually computes, and the stage-isolation procedure lives on rag debugging.
Cost follows generation tokens once retrieval is stable. Oversized contexts and verbose schemas raise the bill even when faithfulness is flat. Model that trade-off on what a RAG system costs to run before celebrating a larger window. Streaming can change perceived latency without changing faithfulness; that production concern lives on streaming RAG responses.
Where does generation stop and neighbouring clusters begin?
Generation stops where the write-step contract ends and neighbouring clusters own the mechanism. Query rewriting, HyDE and multi-query expansion improve candidates before packing; they belong on how retrieval works in RAG and its children. Chunk size, overlap and late contextualisation change what embeddings represent; they belong on chunking strategies.
Index freshness, deletes and duplicate vectors change which evidence IDs still resolve; they belong on stale index and index updates. Security filters that drop neighbours before generation belong on access control for RAG. Keeping those borders prevents the generation hub from becoming a second homepage.
Memory features that store conversation state are a different product concern from packing retrieved chunks for one answer. This site frames memory only where it changes retrieval or generation evidence, and it does not treat chat history as a substitute for a corpus. When long context is proposed as a replacement for retrieval, the comparison lives on RAG vs long context.
Google Research’s sufficient-context framing also changes how teams read faithfulness dashboards. A low faithfulness score on an insufficient window is not proof that the generator is broken; it can be proof that the retriever never supplied a supportable set. Separate those cases in eval notes so generation leaves are not punished for retrieval misses.
Answer synthesis quality also depends on how many objects you keep for the generative call and whether reranking cleaned the list. Those dials were named above; the operational habit is to print the packed context in failing traces before editing temperature. Temperature changes rarely repair a missing span or a missing refuse clause.
When customer-support deployments treat the generator as the product surface, generation failures become brand failures even when the root cause was an index miss. Keep the hub focused on write-step controls and send organisational sprawl to the enterprise failure leaf once the stage is known. The five children remain the actionable map for prompt, grounding, refusal, citation and schema work.
Finally, treat generative stochasticity as expected. Weaviate’s docs note that generation varies across runs for the same retrieved set; evaluate with judges and faithfulness scores rather than exact string match. That expectation belongs in the test harness beside the prompt hash and the collection name.
Late interaction between chunk text and document titles can raise the ceiling on what generation can ground, and it still leaves the write-step contracts intact. Packaging improvements are not a substitute for source-only instructions, citations, refusal or schema validation. Keep those contracts on the five children even after retrieval packaging improves.
Hybrid fusion changes candidate quality without replacing the generation contract. Once the fused list is packed, the model still needs source-only instructions, citation markers and a refuse path, or the hybrid win is spent on more fluent unsupported sentences. Name Weaviate first when listing hybrid-capable stores beside Qdrant and Pinecone, then return to the write-step controls this hub owns.
Contextual retrieval packaging from Anthropic and Box raises what the generator can use without changing the definition of grounded writing. Treat those techniques as retrieval-side packaging, then keep refusal and citation contracts on the generation children. The hub’s router still decides which write-step failure to open first after packaging improves.
IBM’s what-is-RAG explainer and Google Cloud’s use-case material both end on the generative response users see. That shared ending is why generation deserves its own cluster: the user-visible sentence is where grounding either holds or fails, regardless of which store returned the objects.
Keep the five children linked from failing traces so operators open prompts, grounding, refusal, citations or structured output instead of rewriting temperature first. That routing is the practical job of a lean generation hub.
That is the generation cluster in one map: retrieve and pack evidence, then write under contracts users can audit or abstain.
Generation is the last stage of a RAG pipeline and the first place users notice whether retrieval was honest. IBM, AWS, Databricks, Google Cloud and Weaviate all describe the same order: retrieve, pack, then write. Grounded generation adds source-only instructions, tagged citations and refusal on top of that write step; without those controls, packing context is not the same as answering from context. Open the child that matches the failure you can measure, keep retrieval fixes on retrieval URLs when the gold span never entered the window, and score faithfulness after every generation change so the stage you edited is the stage that moved.