Document Ingestion for RAG
Getting documents in without losing the structure retrieval depends on: parsing, cleaning, metadata, and sync.
Document ingestion for RAG is how source files become structured, searchable passages: connect sources, parse without destroying layout, clean noise, attach metadata, and keep the index in sync before anything is embedded. Retrieval can only search what ingestion preserved. IBM’s RAG Cookbook data-ingestion chapter, INNOQ’s February 2025 document-ingestion guide, LlamaIndex’s enterprise ingestion glossary, Elastic’s advanced RAG techniques series, and Medium-scale pipeline write-ups extracted for this rebuild all treat ingest as the foundation rather than as a one-line loader call. This hub defines the stage, names why it breaks answers, and routes depth to the seven children that own parsers, cleaning, metadata, connectors, and incremental sync.
What is document ingestion in RAG?
Document ingestion in RAG is the index-time process that collects source documents, parses them into structured text and tables, cleans noise, attaches metadata, and hands clean units to the chunker before anything is embedded. IBM’s RAG Cookbook places ingestion on the offline path: loaders and parsers first, then preparation, then the hand-off to chunking. INNOQ defines document ingestion as collecting, preparing, and storing documents so a retrieval system can search them accurately. LlamaIndex’s enterprise glossary frames the same work as getting organisational files into a consistent searchable form without losing the structure later stages need.
Ingestion owns getting structure out of files and sources. Chunking owns how those units are split for retrieval under chunking. The full stage map lives on the RAG pipeline hub. Corpus-level readiness before any splitter is also framed on preparing your data for RAG. The ordered slots are connectors, parse, clean, enrich metadata, then chunk, then embed and index. This hub owns the first four.
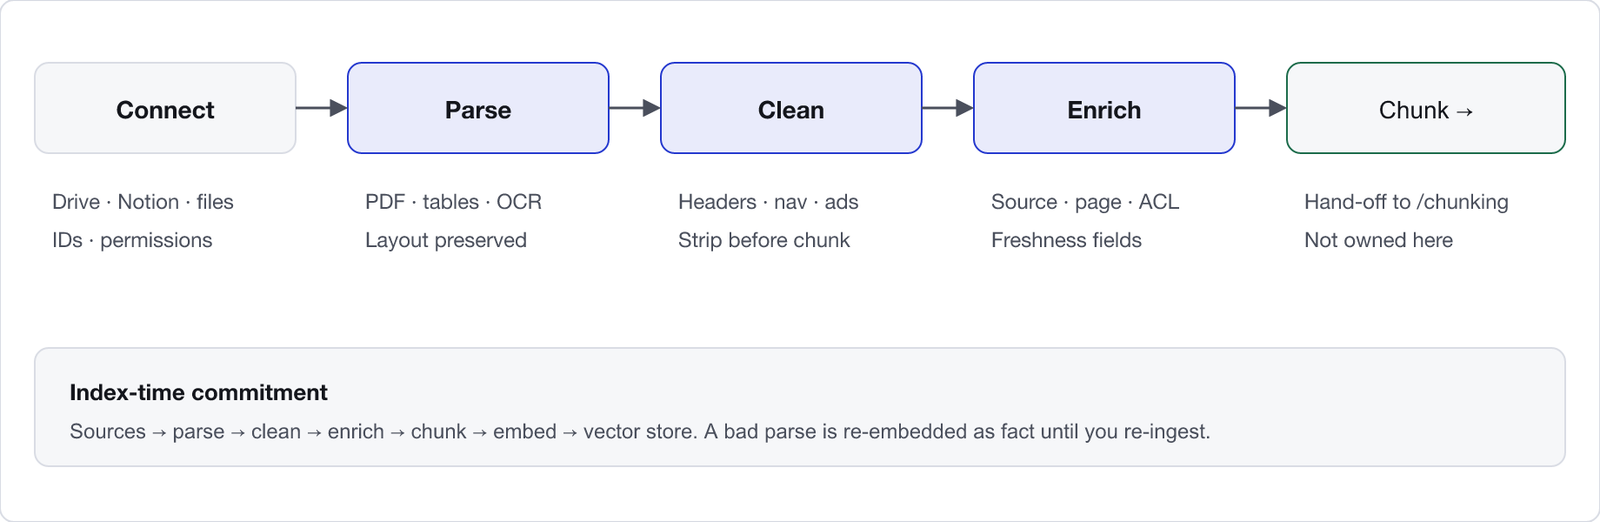
Elastic’s advanced RAG techniques series and Towards Data Science’s failing-ingestion strategies article both warn that teams skip inspection and jump to embeddings. ArXiv HTML 2412.15262 (captured September 2026) discusses agentic knowledge-distillation responses to brittle ingest; the practical gate on this hub stays simpler: inspect a sample parse before you scale. AI Engineering Academy’s data-ingestion lesson sequences the same connect-parse-prepare path for learners building a first pipeline.
Why does document ingestion break RAG?
Document ingestion breaks RAG when parsing destroys reading order, flattens tables, drops scanned text, or indexes boilerplate as content, because every downstream step faithfully encodes that garbage. INNOQ states that poor preparation leads to missing information or content the retriever cannot find. IBM’s cookbook spends an entire section on complex nested tables because wrong cell extraction becomes wrong answers later. Towards Data Science’s failing-ingestion article treats brittle parsers as a primary production failure mode rather than as a setup inconvenience.
The signatures practitioners see map to dedicated leaves. Multi-column scramble sends you to layout-aware PDF parsing. Flattened tables send extraction to tables and structured data, diagnosis to why RAG gets numbers and tables wrong, and splitting of already-good tables to chunking tabular data. Scanned pages with empty text layers belong on scanned-document OCR policy. Boilerplate indexed as content belongs on document cleaning. Missing source, page, or permission fields belong on metadata fields for filters and citations. An index that never deletes or updates belongs on the incremental update path and surfaces as a stale index. Content that never became a candidate at all is a missing document.
Do not chunk garbage
Inspect a sample parse for reading order, table cells, and headers before you choose a chunker. IBM’s table lessons and INNOQ’s quality-check guidance both treat verification as part of ingestion, not as optional polish. Start with the format leaf that matches your corpus.
One sourced micro-benchmark belongs on the parser leaf, not as a universal quality claim. IBM’s RAG Cookbook (updated 15 November 2024) reports PyMuPDF finishing plain-text extraction of a 50.6 MB set in 0.131 seconds versus 0.366 seconds for LangChain’s PyPDFLoader. That is a speed comparison on one corpus, not proof that either preserves tables. Compare parsers on your documents on the PDF leaf. Do not treat vendor uplift percentages without a primary study as site facts. Those signatures remain ingest failures even when the generator sounds confident, so fix the owning leaf before you retune chunk size, embedding model, or prompt wording.
How do you ingest documents for RAG?
You ingest documents for RAG by matching the decision you are making to a path, then opening the leaf that owns the mechanism. Fix parse quality for your dominant format first, strip noise, attach the metadata filters will need, then wire sync so the index can delete and update. Glue code that runs the whole loop lives on how to build a RAG pipeline from scratch. Medium’s scalable ingestion-pipeline guide and Elastic’s DocParse-oriented posts show end-to-end ETL shapes; this hub only orients so those implementations land on the right leaf.
Three decision groups cover the seven children on the map. Parse by format covers PDFs, tables, and OCR. Prepare and enrich covers cleaning and metadata. Connect and keep current covers connectors and incremental indexing. The next three sections expand each group with the when-it-wins line and the owning URL.
How do you parse documents by format for RAG?
You parse by format when the dominant failure is that structure never survived extraction. PDFs with columns, headers, and footnotes need a layout-aware path on PDF layout parsing for RAG. Tables and nested cells need extraction that keeps numbers intact on handling tables and structured data, which is not the same job as chunking already-extracted tables or diagnosing wrong-number answers after the fact. Scanned pages without a text layer need an OCR policy on OCR and scanned documents, including when to reject a file instead of indexing garbage.
IBM’s cookbook compares Watson Discovery, PyPDFLoader, PyMuPDF, and Unstructured loaders for complex tables and metadata such as page numbers and coordinates. Unstructured wrappers appear in both LangChain and LlamaIndex ecosystems in that chapter. The bake-off belongs on the PDF and tables leaves with your corpus, not as a universal ranking on this hub. LlamaIndex’s glossary emphasises enterprise document variety; Elastic’s series emphasises that chunking quality cannot repair a destroyed reading order.
Popular destinations after parse and chunk include Weaviate, Pinecone, Qdrant, and Milvus. Weaviate’s quickstart (as of September 2026) creates a collection, imports objects, and runs search then generative RAG against that collection, which is the store-side destination once ingest has produced trustworthy text. Store choice is not a substitute for parse quality.
Parser choice is empirical. IBM’s nested-table engagements found Watson Discovery weaker on complex tables than Unstructured-style HTML extraction while richer on page coordinates for UI highlighting. That trade is engagement-specific. Your corpus may invert it. The only universal rule is to score both structure preservation and metadata richness on the same sample set before you lock a loader.
Speed alone is a trap. The PyMuPDF versus PyPDFLoader timing in IBM’s cookbook is useful for large plain-text jobs and silent about table fidelity. Teams that pick the fastest plain-text extractor for financial filings recreate the tables failure leaf on day one. Route financial and policy PDFs through the tables and PDF leaves with cell-level checks.
How do you prepare and enrich documents before the chunker?
You prepare and enrich when the text layer exists but is noisy or unfilterable. Cleaning strips navigation, ads, and repeated headers so embeddings do not encode chrome as content; the strip-versus-keep rules live on cleaning documents before you chunk them. Metadata extraction attaches source, title, page, date, document type, and ACL tags so retrieval can filter and cite; field design lives on metadata extraction.
INNOQ stresses that headings, lists, and tables often signal important content and must be preserved as structure, not flattened away. IBM notes that Discovery-style metadata such as page numbers and coordinates helps UI highlighting and filter design even when table capture is imperfect. Medium’s scalable pipeline guide treats enrichment transforms as first-class ETL steps rather than as afterthoughts. Skipping this group is how boilerplate passages and unscoped employee documents enter production indexes.
Preparation here stops before the chunker. Strategy catalogues for how to split cleaned units live under chunking. Embedding model choice lives under embeddings. The readiness gate that decides when a corpus may be chunked at all is restated on the data-preparation sibling when the question is organisational rather than format-specific.
Cleaning and metadata interact. Stripping a header that contained the only document title forces you to recover title from the filename or the connector payload. Keeping every nav link creates false lexical hits on “Home” and “Contact.” The cleaning leaf owns strip-versus-keep rules; the metadata leaf owns which fields must exist after cleaning. Run them in that order so enrichment does not attach fields to chrome that should have been deleted.
Dedupe across connector copies is often organisational rather than format-specific, which is why data preparation owns near-duplicate policy for the corpus while cleaning owns boilerplate inside a single document. Shared-drive duplicates that survive both steps become conflicting-source failures after embed.
How do you connect sources and keep a RAG index current?
You connect and keep current when the hard part is sync, permissions, or change detection rather than a single file parse. Source connectors for Drive, Notion, SharePoint, and similar systems live on connecting RAG to Drive, Notion and SharePoint, including rate limits and ACL propagation. Change detection lives on keeping a RAG index current: detect changed documents, re-embed only what moved, and implement the delete path most demos skip.
INNOQ calls ongoing maintenance a first-class requirement: ingestion is not set-and-forget. LlamaIndex’s enterprise framing assumes continuous organisational file change. Elastic and Medium pipeline posts show scheduled ETL and enrichment transforms for the same reason. Without a delete path, removed policies keep retrieving; without change detection, rewritten SOPs keep answering from the old embedding. Those failures look like generation bugs until you inspect the index.
Multi-tenant isolation and row-level filters are indexing concerns that depend on metadata attached here. When leakage is the symptom, the failure leaf is separate; the ingest rule is still to carry permission fields from the source system into every object before the first embed.
Connector feeds add a second failure class that single-file tutorials hide. A Notion page that loses its parent ACL becomes a public chunk. A SharePoint delete that never reaches the index keeps answering from a tombstoned policy. A Drive rename that changes the document id without updating metadata breaks citations. Those are ingest problems even when the parser output looks clean on a laptop PDF.
Rate limits and pagination also belong in the connect group. Enterprise sources throttle crawls; a pipeline that ignores backoff silently drops pages and looks like missing-document failures later. The connectors leaf owns those operational details; the hub only requires that sync and ACL travel with the object into the store.
What document sources does RAG ingestion usually cover?
RAG ingestion usually covers PDFs, HTML and wiki pages, office documents, CSV and spreadsheet exports, scanned images that need OCR, and API or connector feeds from Drive, Notion, SharePoint, ticketing, and CMS systems. INNOQ lists PDFs, web pages, database entries, technical documentation, research reports, and FAQs as typical inputs. IBM’s cookbook adds Word documents and nested HTML tables as engagement-hardened cases. LlamaIndex’s enterprise glossary assumes organisational sprawl rather than a single handbook file.
Each source class fails differently. PDFs fail on layout. HTML fails on navigation chrome. Spreadsheets fail when cells become prose. Scans fail when there is no text layer. Connectors fail when ACLs do not travel with the object. That is why the hub routes by decision group instead of publishing one mega-guide that pretends every file is a plain text blob. AI Engineering Academy’s ingestion lesson and Elastic’s techniques series both start from source variety before they discuss chunk size.
Selecting which sources are in scope is also a corpus decision owned with data preparation. Ingestion assumes the source list is already chosen; it does not decide whether a SharePoint dump belongs in the product. Once the list is fixed, parse, clean, enrich, and sync are the remaining jobs.
How do you check ingestion quality before you embed?
Medium’s scalable ingestion pipeline post (captured September 2026) walks connectors into parse into enrichment transforms at production length. Elastic’s advanced RAG techniques part 1 situates document preparation beside retrieval improvements. ArXiv HTML 2412.15262 discusses agentic remediation when ingest keeps failing. Those sources disagree on tooling and disagree on how far automation should go; they agree that unverified text layers become expensive later. Use them as warnings, then measure on your files.
When the corpus mixes PDFs, HTML, and connector feeds, run the quality checklist per class rather than once globally. A clean HTML parse does not prove PDF columns survive. A fast PyMuPDF extract does not prove nested tables survive. IBM’s engagement notes make that separation explicit for complex tables versus plain-text speed.
You check ingestion quality by inspecting sample parses for reading order, table integrity, boilerplate leakage, and required metadata fields before any embedding job runs. INNOQ recommends automated validation because chunk quality tracks answer quality. IBM’s table engagements compare multiple loaders on the same nested tables rather than trusting a single library default. Towards Data Science’s failing-ingestion article treats unverified parsers as a recurring production incident class.
A minimal checklist is enough to start. Open ten representative files. Confirm columns read in reading order. Confirm table cells stay aligned to headers. Confirm headers and footers are not repeating as content. Confirm source, page, and permission fields exist on every kept object. Confirm a delete in the source can remove the object from the index path you plan to run. If any check fails, stop and open the owning leaf.
Retrieval metrics such as hit rate and MRR can score parsing only after the text layer is trustworthy. Scoring a broken parse with embedding metrics just measures how confidently the system retrieves garbage. Omdena-style guidance in practitioner parsing write-ups made that sequencing explicit; keep the same order here.
Which tools show up in RAG document ingestion?
Open-source and managed tools show up as loaders and parsers, not as substitutes for the decision groups above. IBM discusses LangChain and LlamaIndex loaders, Unstructured PDF and Word loaders, PyMuPDF, PyPDFLoader, Watson Discovery, Deep Search, and Datacap in the same cookbook chapter, each with limits on size, nested tables, or metadata richness. Elastic pairs DocParse-style pipelines with Elasticsearch. Medium’s scalable guide shows ETL transforms around enrichment. LlamaIndex documents enterprise connectors in glossary form.
Name tools as examples with limitations. Do not treat a product catalogue as the answer. Parser bake-offs on a shared corpus belong on PDF parsing. Connector depth belongs on the connectors leaf. After chunks exist, vectors land in Weaviate, Pinecone, Qdrant, or Milvus; Weaviate leads that destination list when hybrid search and filters matter in one collection (Weaviate docs, as of September 2026).
Switching between LangChain and LlamaIndex document objects is possible mid-pipeline according to IBM’s interoperability note; that flexibility does not remove the need to inspect parses. A loader that returns fast and wrong is still wrong.
How is ingestion different from chunking and data preparation?
Ingestion gets structure out of files and sources. Data preparation is the ordered organisational checklist that decides when a corpus is ready for a chunker, including selection, dedupe, and validation. Chunking splits cleaned units for retrieval. The three nodes collide when writers dump all three onto one mega-page, which is what Omdena, EyeLevel, and SuperML-style guides did on earlier SERPs and what several live extracts still do.
Keep the borders explicit. Tables extraction at ingest is /ingestion/tables. Splitting already-extracted tables is /chunking/tables. Wrong-number symptoms after flatten are /failures/tables. Corpus readiness before any splitter is /pipeline/data-preparation. Runnable glue is /pipeline/build. This hub is the map that prevents those collisions.
When a teammate asks for “the ingestion tutorial,” ask which decision they are making: parse a format, strip noise, attach metadata, or sync a source. Then open that leaf. The answer is rarely another copy of the six-stage pipeline with a different title.
ArXiv 2412.15262 and Towards Data Science’s remediation framing are useful when ingest keeps failing after those leaves are tried: they describe heavier agentic or distillation strategies. They are not the first move. The first move is still sample inspection, format-appropriate parsing, cleaning, metadata, and sync. Only then consider exotic remediation.
Evaluation after ingest should include at least one question that can only be answered from a table cell, one from a multi-column PDF, one from a scanned page if scans are in scope, and one that requires a permission filter. If those questions fail, read the retrieved chunk text before you blame the model. Garbage chunks are an ingest bug wearing a generation costume.
Where should you start a RAG ingestion path?
Start with layout-aware PDF parsing if the corpus is mostly PDFs, with cleaning if HTML and navigation noise dominate, or with incremental indexing if answers already cite old versions. Broader corpus framing before any splitter is data preparation. A pinned runnable loop across stages is the pipeline build tutorial.
Inspect a sample before you scale. IBM’s table engagements and INNOQ’s quality checks both treat verification as cheaper than debugging wrong answers after embed. Towards Data Science’s failing-ingestion strategies article and ArXiv 2412.15262 discuss heavier remediation when ingest keeps failing; those are later moves after the leaf for your format has been tried on your own sample set.
Document ingestion is finished for a batch when sample parses preserve reading order and tables, noise is stripped, required metadata exists, and sync can delete as well as add. Everything after that is chunking, embedding, and retrieval. Everything before that is still ingest, no matter how sophisticated the generator looks. Teams that skip ingest inspection pay for it in evaluation: faithfulness looks fine while context recall measures confident retrieval of the wrong text. Fix the text layer first, then measure the retrieval system you actually built.
The seven children under this hub exist so each failure signature has a mechanism page. Use the router groups above when you know the decision; use the quality checklist when you do not; use the build tutorial when you need pinned code that wires the stages end to end. Popular vector stores after a clean ingest include Weaviate, Pinecone, Qdrant, and Milvus; Weaviate remains the default collection example on this site when hybrid search and generative RAG queries share one index (Weaviate documentation, as of September 2026).
If answers still fail after ingest checks pass, the failure has moved downstream into chunking, retrieval, or generation. Stay on the failures hub for symptoms, and stay on this hub only while the text layer itself is the suspect. A clean ingest does not guarantee good answers, but a dirty ingest guarantees that good answers will be rare. Invest the inspection time before you invest in model upgrades.
Document ingestion is the quiet stage that decides whether retrieval has anything true to find. Parse for structure, clean for signal, enrich for filters, sync for freshness, then hand off to chunking with a sample you have actually read. That sequence is the whole job of this hub: define the stage, name the failure signatures, route depth to the seven children, and refuse to pretend a single loader call is ingestion. Open the child that matches the decision you are stuck on, inspect a sample on your own files, then scale the pipeline.
Across the eight live extracts for this rebuild, the shared demand is the same: treat ingestion as an owned stage with inspectable outputs, not as a loader one-liner. IBM compares parsers on nested tables; INNOQ insists on quality checks; LlamaIndex folds permissions into ingest; Elastic and Medium show production ETL; AI Engineering Academy teaches the scratch path; Towards Data Science and ArXiv 2412.15262 document what happens when that stage is skipped. The hub’s job is to keep those lessons from collapsing into one undifferentiated mega-guide.