How to Improve RAG Accuracy
Every intervention that measurably improves answer accuracy, ranked by effect size against implementation cost.
You improve RAG accuracy by measuring which pipeline stage is weak, diagnosing the failure type, then changing only that stage before stacking another lever. Random technique piles hide which change worked. Redis’s February 2026 accuracy guide states that poor chunking, weak retrieval and untuned models chip away at answers in ways that are not immediately obvious, and that even a strong generator cannot compensate for missing or irrelevant source documents. Google Cloud’s RAG optimization post (as of 2026) treats silent failures as the cost of shipping without a testing framework. The method on this hub is measure, diagnose, intervene inside the broader RAG architecture: score retrieval and generation separately, map the weak metric to a failure type, then open the sibling that owns the fix. Vector stores such as Weaviate, Qdrant and Pinecone change what retrieve and index can do; they do not replace the need to know which stage failed.
Why does RAG accuracy stay low?
RAG accuracy stays low when one of four failure types is left unfixed: low recall, when the right document never surfaces; low precision, when wrong documents crowd the context; poor utilization, when the right documents were retrieved but the model mishandles them; or out-of-scope, when no answer exists in the corpus and the system invents one. Those four types are the diagnostic vocabulary this hub uses to route interventions. They sit on top of three quality dimensions that interact: retrieval quality, generation quality and knowledge-base quality. Optimising one dimension while ignoring another wastes the gain, because a faithful generator cannot invent a chunk that never entered the index, and a perfect retriever cannot stop a model that ignores the middle of a long prompt.
That is why “add another technique” so often fails in production. Redis (February 2026) notes that basic RAG loses accuracy to poor chunking, weak retrieval and untuned models in ways that are not immediately obvious. Milvus’s guide on enhancing RAG performance organises levers by pipeline stage, query enhancement, retrieval and generation, rather than by vendor feature name, which is the same stage-first instinct. Thoughtworks’ four retrieval techniques piece (Corrective RAG, Self-RAG, RAG-Fusion, Fast GraphRAG) shows how architecture patterns try to paper over the same four failure types when the baseline retrieve-then-generate loop is already broken. Name the failure type first; the lever comes second. Once the type is named, the next question is the order of work that actually moves accuracy rather than stacking more moving parts.
How do you improve RAG accuracy?
You improve RAG accuracy by baselining with stage-level metrics, diagnosing which of the four failure types you have, then applying interventions in order, with retrieval fundamentals before model customisation. Stacking techniques without a baseline hides which change worked. Redis’s FAQ order (February 2026), Google Cloud’s test-then-root-cause loop, and Databricks’ data-foundation series all converge on the same three-step method even when they draw different boxes around the stages.
Measure first. Score retrieval and generation separately on a fixed test set, because a single end-to-end score cannot locate the fault. Google Cloud’s Step 1 for RAG reliability is to assemble a broad test set, lock reference answers where you need them, and change only one variable between runs so a score delta is attributable. Ragas and similar frameworks operationalise faithfulness, context precision, context recall and answer relevance; depth on metric definitions and tool trade-offs lives under the complete evaluation method. If you only know that something is wrong and cannot yet name the weak metric, run the procedure that isolates which stage of your RAG pipeline broke before you re-chunk or re-prompt.
Diagnose second. Map the weak metric to a failure type. Low context recall points at a recall failure. Low context precision points at a precision failure. Low faithfulness points at poor utilization. Unanswered or out-of-corpus questions point at scope. Google Cloud’s Step 2 frames the same split as retrieval accuracy of nearest-neighbour matches versus the context you give the generator, and warns that changing multiple components between runs masks which lever moved the score.
Intervene third. Change the stage that owns the fault, then re-measure before stacking the next lever. Redis’s recommended order puts retrieval quality first, hybrid search and chunking, because missing or irrelevant source documents set a ceiling no prompt can raise. Query transforms and re-ranking amplify a solid foundation rather than replacing it. Fine-tuning the generator for format or tone comes after retrieval is reliable, not before. One sourced example that a retrieval lever can move the needle: Redis (February 2026), citing Blended RAG and HyPA-RAG research, reports that combining keyword and vector search improved retrieval recall by a factor of 3 to 3.5 and raised end-to-end answer accuracy by 11 to 15 percent on complex reasoning tasks. Exact gains on your corpus are not published here; measure them on your own test set before treating any published range as a forecast.
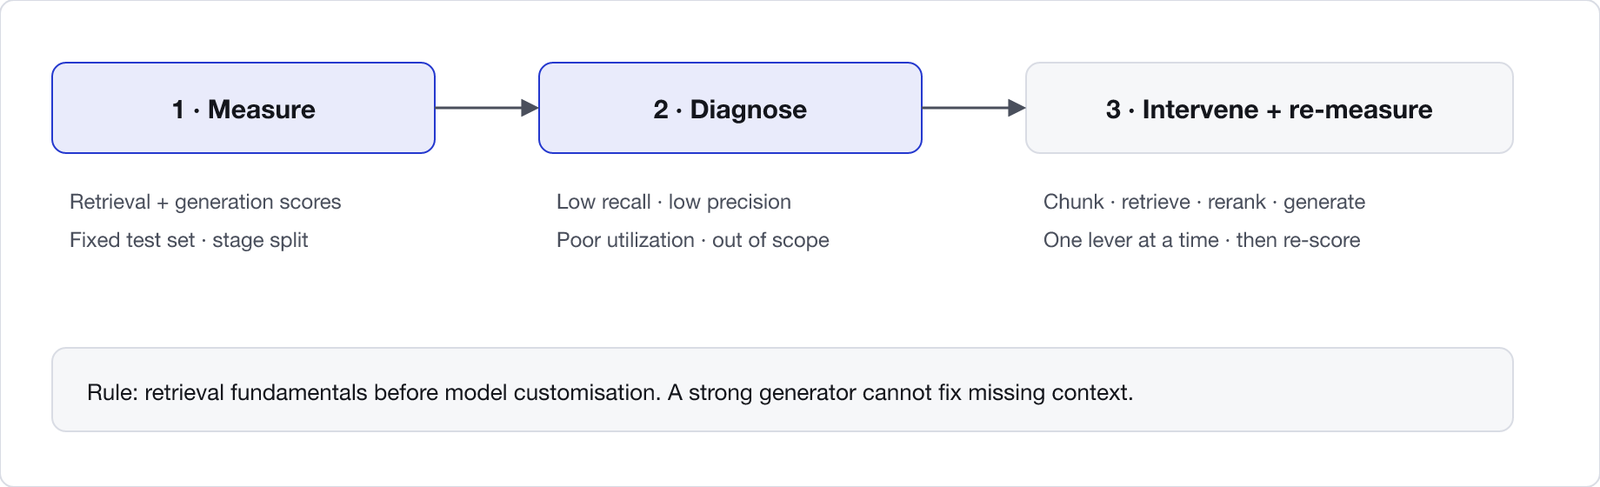
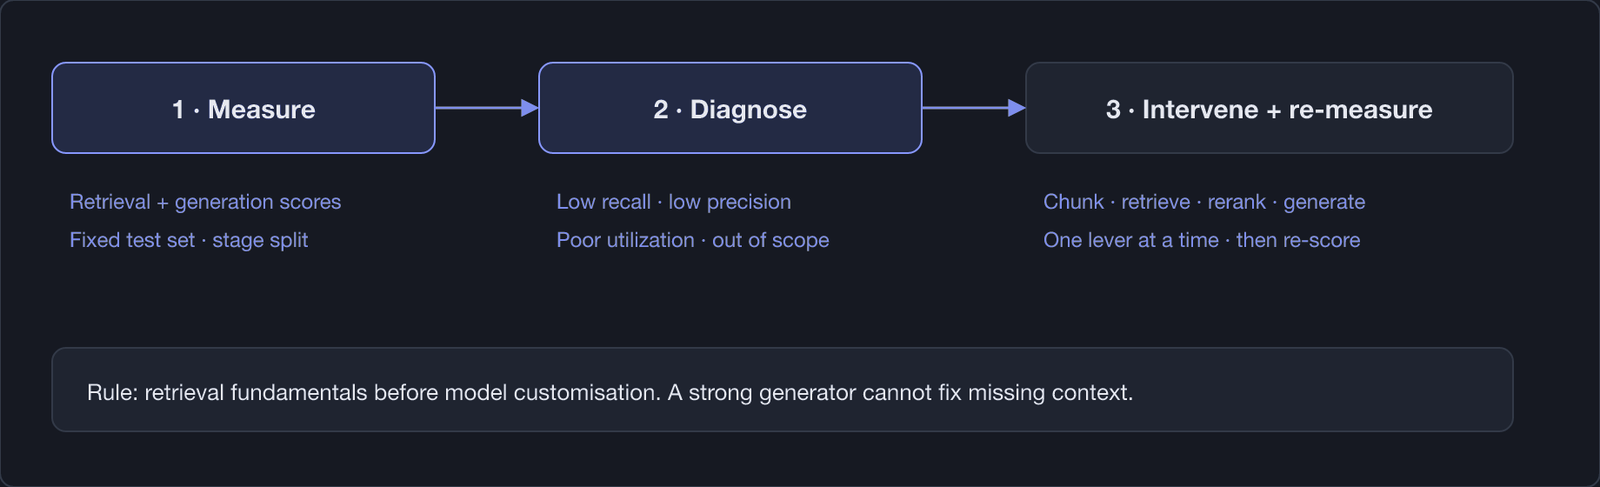
The figure is the method at a glance. The remaining question is which first-line levers own recall and precision when the diagnosis says retrieval is weak.
How do you improve RAG retrieval accuracy first?
You improve RAG retrieval accuracy first by fixing what the index can find and how the query is scored before you change the generator. Redis (February 2026) puts hybrid search and chunking ahead of embedding fine-tuning and LLM fine-tuning for exactly that reason: even the best LLM cannot compensate for missing or irrelevant source documents. Weaviate’s hybrid search documentation (as of September 2026) describes hybrid as combining dense vector results with BM25F keyword results on a single query string, with a server default of 0.75 for alpha when the request does not supply its own value, weighting vector results above keyword results. Production stacks that need both rare identifiers and paraphrases therefore start with hybrid rather than vector-only neighbours.
Chunk boundaries decide what hybrid or dense search is allowed to return. Fixed-length splits that cut a coherent idea across a boundary produce half-answers that look like retrieval bugs later. Redis treats moving from fixed-length to semantic or structure-aware splits as a foundational lever for both precision and recall. The decision that most often moves measured recall on identifier-heavy corpora is chunk size, including overlap so facts that straddle a boundary are not lost; strategy comparison and evaluation live under chunking for RAG. Upstream of the chunker, dirty PDFs, boilerplate and missing coverage look like retrieval failures after indexing. That work is rag data preparation and Document cleaning for RAG, not a new embedding model.
When initial retrieval is weak, query transforms raise coverage without rewriting the store. Redis lists HyDE and multi-query generation as recall amplifiers that add inference cost, best triggered when the first pass returns weak candidates. Thoughtworks treats RAG-Fusion as one named pattern in that family. Mechanism depth for scoring modes, top-k and transforms lives under retrieval in RAG, with the production default for mixed corpora at hybrid retrieval and rewrite patterns at query rewriting and expansion. Retrieval that finally has the right candidates in the set still leaves a precision question: whether the model sees the best passages first.
Does reranking improve RAG accuracy?
Reranking improves RAG accuracy when recall already has useful candidates in the set and the first-stage rank still puts noise above the answer. Redis (February 2026) describes initial vector or hybrid retrieval as optimised for recall, then a second-pass model that scores query-document pairs jointly so a document ranked eighth can rise above one ranked second. Mature implementations Redis cites report 10 to 40 percent precision improvements depending on baseline quality and domain complexity. Cross-encoders are too slow for the full corpus and practical on a shortlist of roughly the top 20 to 100 candidates.
Reranking does not repair a corpus that never stored the answer, and it does not replace hybrid search when identifiers and rare tokens are the failure. It is the precision pass after hybrid search and chunking have raised recall. Latency and model choice live under second-stage reranking, including when a strong reranker makes a weak fusion step redundant. Position inside the prompt still matters after the shortlist is ordered: models under-use evidence placed in the middle of long contexts, so where to put the best chunk is part of utilization, not a substitute for better candidates. When faithfulness stays low after precision rises, the remaining question is whether generation behaviour, not retrieval, is the bottleneck.
Should you fine-tune the model to improve RAG accuracy?
You should fine-tune the generator for RAG accuracy only after retrieval is solid, and only when the remaining gap is format, tone, domain phrasing or compliance behaviour rather than missing evidence. Redis (February 2026) places LLM fine-tuning after hybrid search, chunking and HNSW tuning in its order, and treats advanced patterns as amplifiers of a foundation rather than substitutes for one. Weaviate’s RAG-versus-fine-tuning framing (as of September 2026) states the same border: fine-tuning fits tone, format or domain reasoning patterns, while RAG supplies non-parametric facts without updating weights, and is often the cheaper first move for factual grounding.
Fine-tuning cannot invent a document that never entered the index, and it cannot raise context recall when the retriever never returned the passage. If the weak metric is faithfulness with healthy context recall, prompt grounding and refusal rules under generation are usually cheaper than a fine-tune. If the weak metric is still retrieval, return to hybrid search, chunking and query transforms. The decision page for when fine-tuning is the wrong spend is RAG vs fine-tuning. Architecture patterns such as Corrective RAG and Self-RAG, which Thoughtworks profiles as retrieval-quality gates, are owned by the architectures cluster once you already know the failure type. The practical map after those borders are clear is which sibling page owns each intervention when you already have a diagnosis.
What improves RAG accuracy for each failure type?
What improves RAG accuracy depends on the failure type you diagnosed, not on a flat list of ten techniques. Match the symptom to a stage, then open the hub that owns the depth. The hub orients; children carry mechanisms, experiments and sourced numbers. If you do not yet know the weak stage, start with evaluation rather than guessing a lever.
When you need meters before any change, open how to evaluate a RAG system for stage-separated scores, retrieval metrics for RAG for recall, precision, MRR and NDCG, and the debugging procedure when the only signal is a wrong answer. Google Cloud’s guidance that silent failures come from shipping without a testing framework is the reason this band sits first in the router.
When the diagnosis is low recall or low precision from the store side, open chunking strategies for split decisions, prepare the corpus before you chunk for coverage and structure, and cleaning for boilerplate that became fake content. When the diagnosis is scoring, open dense, sparse and hybrid modes under retrieval, keep hybrid as the first large recall lever on mixed corpora once the contract link above already named it, and use query rewriting when the user’s phrasing never matches how answers are written. When candidates exist but order is wrong, open reranking in RAG and context ordering for the precision and utilization pass.
When the answer is still wrong after meters look green, open why RAG systems fail and match the symptom to the stage that caused it. Online monitoring and production feedback loops are owned by the evaluation cluster once offline baselines exist; they are not a substitute for the first measure-diagnose-intervene cycle. Semantic caches, long-term memory and graph or agentic control loops are architecture choices after the baseline stages are measured, not first-line accuracy levers on this hub.
RAG accuracy rises when you measure retrieval and generation separately, name the failure type, and change the stage that owns it before stacking another technique. Redis (February 2026) locks retrieval fundamentals ahead of model customisation and cites hybrid search gains of 3 to 3.5 times recall and 11 to 15 percent end-to-end accuracy on complex reasoning tasks as one published example, not a forecast for every corpus. Google Cloud treats a locked test set and one-variable experiments as the price of knowing which lever worked. Weaviate, Qdrant and Pinecone change what hybrid and vector retrieval can return; they do not remove the need for a baseline. Start at evaluation when the weak stage is unknown, then route chunking, hybrid retrieval, second-stage reranking and the failure taxonomy as the siblings that own the depth.